Designing chips for the AI era: what TSMC’s roadmap means
About twenty years ago I worked with Cliff Hou, LC Lu, and the TSMC PDK team on reference flows with emerging EDA and IP companies. This was the precursor to the OIP. Having a person with LC Lu’s depth of R&D experience running the TSMC Design & Technology Platform is truly an honor, absolutely.
약 20년 전, 저는 클리프 후(Cliff Hou), LC 루(LC Lu), 그리고 TSMC PDK 팀과 함께 신흥 EDA 및 IP 기업들을 위한 레퍼런스 플로우 분야에서 협업했습니다. 이는 OIP의 전신이었습니다. LC 루의 깊이 있는 연구개발(R&D) 경험을 갖춘 인물이 TSMC 디자인 앤드 테크놀로지 플랫폼(Design & Technology Platform)을 이끌게 된 것은 진심으로, 절대적으로 큰 영광입니다.
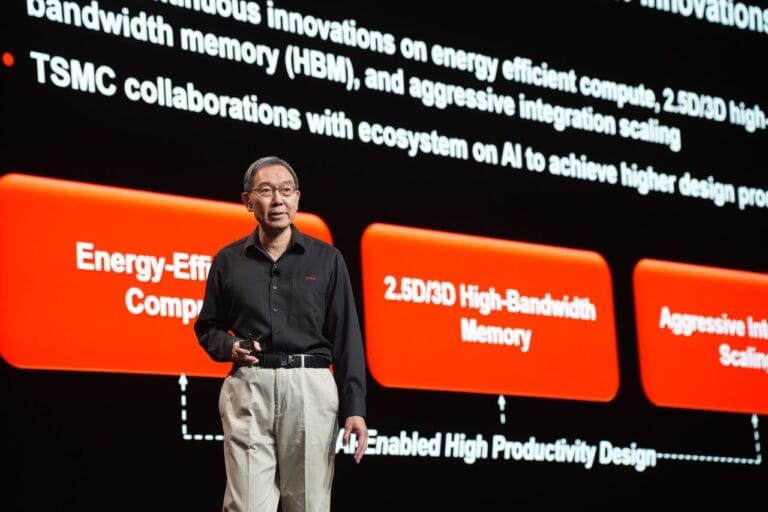
AI is creating two related problems for semiconductor designers. They must deliver more computing power for training and inference, while keeping energy use and cost manageable. Dr. LC Lu’s presentation at the TSMC Open Innovation Platform Forum describes a response built around more efficient transistors, closer integration of logic and memory, larger multi-chip packages, optical connections, and AI-assisted chip design.
인공지능(AI)은 반도체 설계자들에게 두 가지 연관된 문제를 안겨주고 있습니다. 이들은 에너지 사용량과 비용을 관리 가능한 수준으로 유지하면서, 학습 및 추론을 위한 더 많은 연산 능력을 제공해야 합니다. LC 루 박사가 TSMC 오픈 이노베이션 플랫폼(Open Innovation Platform) 포럼에서 발표한 내용은 더욱 효율적인 트랜지스터, 로직과 메모리의 긴밀한 통합, 대형 멀티칩 패키지, 광학 연결, 그리고 AI 보조 칩 설계를 바탕으로 구축된 대응 방안을 설명합니다.
The central challenge is useful work per unit of energy. An AI system’s cost is shaped not only by how quickly its processors calculate, but also by how much power they draw and how efficiently they receive data. Training a model requires immense computation. Serving that model to users adds a different burden: every generated token consumes processing, memory access and communication capacity. As inference use grows, small improvements in energy per token can have large effects across a data center.
핵심 과제는 에너지 단위당 유용한 작업량입니다. AI 시스템의 비용은 프로세서의 연산 속도뿐만 아니라, 소비하는 전력량과 데이터를 얼마나 효율적으로 전송받는지에 의해서도 좌우됩니다. 모델을 학습시키는 데는 막대한 연산이 필요합니다. 해당 모델을 사용자에게 서비스하는 과정에는 또 다른 부담이 따릅니다. 생성되는 모든 토큰은 연산, 메모리 접근, 그리고 통신 용량을 소비합니다. 추론 사용량이 증가함에 따라, 토큰당 에너지 소비량의 작은 개선도 데이터 센터 전체에 걸쳐 큰 파급 효과를 낼 수 있습니다.
The first part of TSMC’s approach is continued process improvement. New semiconductor processes can improve power, performance and area, the three measures commonly shortened to PPA. The presentation discusses nanosheet transistors and design technology co-optimization, in which engineers adapt circuit design and manufacturing technology together. A transistor alone does not determine a chip’s efficiency. Standard-cell layouts, wiring, placement and the demands of a particular workload all affect the result. TSMC has described its NanoFlex family as giving designers choices that help balance performance and energy efficiency.
TSMC 접근 방식의 첫 번째 부분은 지속적인 공정 개선입니다. 새로운 반도체 공정은 전력, 성능, 면적을 향상시킬 수 있으며, 이 세 가지 지표는 통상적으로 PPA로 줄여서 불립니다. 해당 발표에서는 나노시트 트랜지스터와 더불어 엔지니어들이 회로 설계와 제조 기술을 함께 조정하는 설계-공정 공동 최적화(DTCO)에 대해 다룹니다. 트랜지스터 하나만으로는 칩의 효율성이 결정되지 않습니다. 표준 셀 레이아웃, 배선, 배치, 그리고 특정 워크로드의 요구사항 모두가 결과에 영향을 미칩니다. TSMC는 나노플렉스(NanoFlex) 패밀리가 설계자들에게 성능과 에너지 효율의 균형을 맞추는 데 도움이 되는 선택지를 제공한다고 설명해 왔습니다.
Those choices matter because AI hardware is not uniform. A component designed for maximum speed may justify a different circuit layout from one designed for lower power or smaller area. Even within a single system, designers may use different kinds of cells where speed is critical and where it is less important. This is a practical limit on any simple claim that a newer manufacturing process will automatically make every AI workload cheaper: designers still have to turn the process’s capabilities into a working product.
AI 하드웨어가 획일적이지 않기 때문에 이러한 선택지들은 중요합니다. 최고 속도를 위해 설계된 부품은 저전력이나 소형 면적을 위해 설계된 부품과는 다른 회로 레이아웃이 필요할 수 있습니다. 단일 시스템 내에서도 설계자는 속도가 결정적으로 중요한 곳과 그렇지 않은 곳에 서로 다른 종류의 셀을 사용할 수 있습니다. 이는 더 새로운 제조 공정이 모든 AI 워크로드를 자동으로 더 저렴하게 만들어 줄 것이라는 단순한 주장에 대한 현실적인 한계입니다. 설계자는 여전히 공정의 역량을 작동 가능한 제품으로 구현해내야 합니다.
The second part of the roadmap moves beyond the individual chip. AI processors need to exchange enormous amounts of data with high-bandwidth memory, or HBM. If computation becomes faster while memory access does not, processors can spend time waiting for data. Placing memory close to compute through advanced packaging increases the bandwidth available between them and can reduce the energy needed to move each bit. The presentation discusses a hierarchy of memory technologies rather than one universal replacement, reflecting different trade-offs in capacity, bandwidth, latency and power.
로드맵의 두 번째 부분은 개별 칩을 넘어섭니다. AI 프로세서는 고대역폭 메모리(HBM)와 방대한 양의 데이터를 교환해야 합니다. 메모리 접근 속도는 그대로인데 연산만 빨라진다면, 프로세서는 데이터를 기다리는 데 시간을 허비하게 될 수 있습니다. 첨단 패키지를 통해 메모리를 연산 장치 가까이에 배치하면 둘 사이의 가용 대역폭이 증가하고 비트당 이동에 필요한 에너지를 줄일 수 있습니다. 이번 발표에서는 하나의 보편적인 대체 기술 대신, 용량, 대역폭, 지연 시간, 전력 측면의 서로 상충하는 요구(trade-off)를 반영한 메모리 기술 계층 구조를 논의합니다.
Advanced packaging also lets designers combine multiple computing dies in one system. TSMC’s CoWoS technology is an example of this approach, while its 3DFabric portfolio includes three-dimensional stacking. The attraction is scale: engineers can bring together more logic and memory than would fit comfortably on one conventional die. The difficulty is that package size, electrical connections, heat removal, power delivery, testing and manufacturing yield all become system-level design problems. TSMC’s 2026 forum materials place 3DFabric and advanced packaging alongside its leading-edge processes as essential parts of future AI design.
첨단 패키지를 통해 설계자는 여러 개의 컴퓨팅 다이를 하나의 시스템으로 결합할 수도 있습니다. TSMC의 CoWoS 기술이 이러한 접근 방식의 사례이며, 3DFabric 포트폴리오는 3차원 적층을 포함합니다. 이 방식의 매력은 확장성에 있습니다. 엔지니어들은 기존의 단일 다이에 편안하게 들어가지 않을 만큼 더 많은 로직과 메모리를 함께 집약할 수 있습니다. 어려운 점은 패키지 크기, 전기적 연결, 방열, 전력 공급, 테스트, 제조 수율 등이 모두 시스템 수준의 설계 문제로 대두된다는 것입니다. TSMC의 2026년 포럼 자료는 3DFabric과 첨단 패키지를 최첨단 공정과 나란히 미래 AI 설계의 필수 요소로 제시하고 있습니다.
As systems grow, communication between them becomes another constraint. The presentation points to TSMC-COUPE, its compact optical engine, as a path toward high-bandwidth, energy-efficient networking. Optical links use light to carry information and may help where electrical links become costly in power or difficult to scale over distance. This does not mean every wire inside a chip disappears. It means designers are looking for the right connection at each level—from circuitry within a die to communication between large AI systems. TSMC lists co-packaged optics among the technologies featured at its 2026 forum.
시스템이 성장함에 따라 이들 간의 통신은 또 다른 제약 사항이 됩니다. 이번 발표에서는 고대역폭의 에너지 효율적인 네트워킹을 향한 경로로서 소형 광학 엔진인 TSMC-COUPE를 지목합니다. 광 링크는 빛을 이용해 정보를 전달하며, 전기 링크의 전력 소모가 커지거나 장거리 전송 시 확장하기 어려운 영역에서 도움이 될 수 있습니다. 이는 칩 내부의 모든 배선이 사라진다는 의미가 아닙니다. 다이 내부의 회로부터 대규모 AI 시스템 간의 통신에 이르기까지, 설계자가 각 계층에 적합한 연결 방식을 찾고 있다는 뜻입니다. TSMC는 2026년 포럼에서 다뤄진 기술 중 하나로 광·전 공동 패키징(CPO)을 꼽고 있습니다.
The presentation’s other major theme is design productivity. More elaborate processes and packages create more decisions for engineers and more conditions their designs must satisfy. Electronic design automation, or EDA, tools already help turn a circuit plan into a physical layout and check whether it can be manufactured. The presentation describes a proposed AI-oriented design enablement kit and agent-based workflows that could help optimize placement and routing, identify and fix design-rule violations, migrate existing designs, and translate descriptions of three-dimensional chip architectures into a standard design format.
발표의 또 다른 주요 주제는 설계 생산성입니다. 더욱 정교해진 공정과 패키지는 엔지니어들에게 더 많은 의사결정을 요구하며, 설계가 충족해야 할 조건도 늘어나게 합니다. 전자 설계 자동화(EDA) 툴은 이미 회로 계획을 물리적 레이아웃으로 변환하고 제조 가능 여부를 검증하는 데 도움을 주고 있습니다. 이번 발표에서는 배치 및 배선 최적화, 설계 규칙 위반 식별 및 수정, 기존 설계 마이그레이션, 3차원 칩 아키텍처 설명을 표준 설계 형식으로 변환하는 작업을 도울 수 있는 AI 기반 설계 인에이블먼트 키트(DEK) 및 에이전트 기반 워크플로를 제안합니다.
These are consequential tasks, but automation must be judged by the quality of the finished design, not only by how quickly a tool produces an answer. A proposed change still has to meet electrical, thermal, timing and manufacturing requirements. An AI agent may generate options and run repeated tool flows around the clock; engineers and verified design tools must establish that the result works. TSMC describes autonomous AI workflows with its ecosystem partners as a focus of the 2026 forum, while its established Open Innovation Platform brings together design tools, intellectual property and manufacturing guidance.
이러한 작업들은 중요하지만, 자동화는 툴이 얼마나 빨리 답을 내놓는가뿐만 아니라 완성된 설계의 품질로 평가받아야 합니다. 제안된 변경 사항은 여전히 전기적, 열적, 타이밍 및 제조 요구사항을 충족해야 합니다. AI 에이전트는 옵션을 생성하고 24내내 반복적인 툴 플로우를 실행할 수 있지만, 결과물이 작동함을 입증하는 것은 엔지니어와 검증된 설계 툴의 몫입니다. TSMC는 2026년 포럼의 초점으로 생태계 파트너들과의 자율형 AI 워크플로를 설명하고 있으며, 기존의 오픈 이노베이션 플랫폼은 설계 툴, 지식 재산(IP), 제조 지침을 하나로 모으고 있습니다.
Shared design descriptions matter in this setting. LC Lu discusses 3Dblox as a way to describe complex multi-die architectures so that different tools and organizations can work from consistent information. TSMC previously introduced 3Dblox for three-dimensional chip design, with the goal of improving interoperability among design tools. For a package assembled from several dies, that common representation can reduce the risk that teams make incompatible assumptions about connections or physical arrangement.
이러한 환경에서는 공유되는 설계 설명이 중요합니다. LC 루는 복잡한 멀티 다이 아키텍처를 설명하는 방법으로 3Dblox를 논의하며, 이를 통해 서로 다른 툴과 조직이 일관된 정보를 바탕으로 협업할 수 있다고 설명합니다. TSMC는 설계 툴 간의 상호 운용성 향상을 목표로 3차원 칩 설계를 위한 3Dblox를 이전에 도입한 바 있습니다. 여러 다이로 조립된 패키지의 경우, 이러한 공통 표현은 팀 간에 연결이나 물리적 배치에 대해 상호 호환되지 않는 가정(assumption)을 내릴 위험을 줄여줄 수 있습니다.
Bottom line: AI progress increasingly depends on improving a whole computing system, not merely making one processor faster. Memory bandwidth, package integration, networking, energy supply and the time needed to design and validate a product can each become the limiting factor. TSMC’s presentation describes these constraints as connected engineering problems: improve the silicon, bring components closer together, move data more efficiently and help designers manage the resulting complexity.
결론: AI의 진화는 단일 프로세서의 속도를 높이는 것을 넘어, 컴퓨팅 시스템 전체를 개선하는 것에 점점 더 의존하고 있습니다. 메모리 대역폭, 패키지 통합, 네트워킹, 전력 공급, 그리고 제품의 설계 및 검증에 소요되는 시간은 각각 병목 요인이 될 수 있습니다. TSMC의 발표는 이러한 제약 사항들을 연결된 엔지니어링 문제로 규정합니다. 즉, 실리콘을 개선하고, 부품들을 더 가깝게 배치하며, 데이터를 더 효율적으로 이동시키고, 설계자들이 그로 인한 복잡성을 관리할 수 있도록 돕는 것입니다.