The Intelligence Revolution: TSMC’s OIP Ecosystem Forges the Path to Trillion-Transistor AI Systems

At the 2026 OIP Ecosystem Forum, the industry narrative shifted from incremental scaling to what TSMC defines as the “Intelligence Revolution.” Akin to the 18th-century Industrial Revolution which transitioned human physical labor to mechanical power, the current era is augmenting human ingenuity through artificial intelligence. We are seeing the birth of workload-specific architectures where AI and human creativity operate in a continuous, high-performance feedback loop.
2026년 OIP 생태계 포럼에서 산업계의 패러다임은 점진적인 미세화(scaling)에서 TSMC가 정의하는 이른바 ‘지능 혁명(Intelligence Revolution)’으로 전환되었습니다. 18세기 산업혁명이 인간의 육체노동을 기계 동력으로 대체했듯, 현재의 시대는 인공지능을 통해 인간의 독창성을 증강하고 있습니다. 우리는 AI와 인간의 창의성이 지속적이고 고성능의 피드백 루프 안에서 작동하는 작업 부하 전용 아키텍처의 탄생을 목격하고 있습니다.
More Than Two Decades of Collaboration: The OIP Foundation
The Open Innovation Platform (OIP) has matured over twenty years from a standard design-center initiative into the industry’s most formidable collaborative engine. What began as a nascent effort to simplify the path to silicon has expanded into a 90-member powerhouse across six specialized alliances: the Design Center Alliance (DCA), EDA Alliance, IP Alliance, Cloud Alliance, VCA Alliance, and the 3DFabric Alliance.
개방형 혁신 플랫폼(OIP)은 지난 20년 동안 표준적인 디자인 센터 이니셔티브에서 업계 가장 강력한 협업 엔진으로 성숙해졌습니다. 실리콘으로 가는 길을 단순화하려는 초기 노력으로 시작된 것이 디자인 센터 얼라이언스(DCA), EDA 얼라이언스, IP 얼라이언스, 클라우드 얼라이언스, VCA 얼라이언스, 3DFabric 얼라이언스의 6개 전문 얼라이언스에 걸쳐 90개의 회원사를 보유한 거대 조직으로 확장되었습니다.
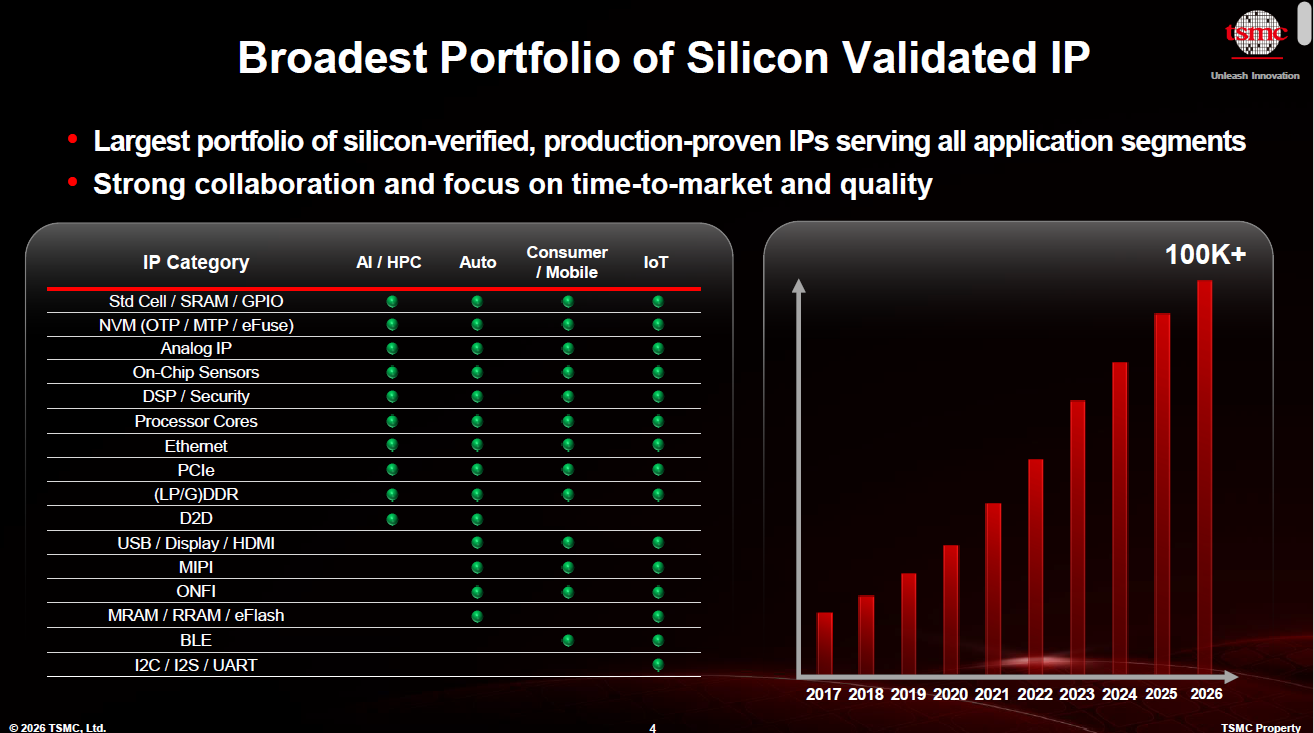
The scale of this ecosystem is best reflected in its portfolio of over 100,000 silicon-verified, production-proven IP titles. This repository isn’t just for the hyperscalers but increasingly targeted at “Physical AI” too for the migration of advanced intelligence into IoT, automotive, and edge devices. By providing these production-proven building blocks, TSMC ensures that the path to a trillion-transistor system is gated by creativity, not by the fundamental physics of IP validation.
이 생태계의 규모는 100,000개 이상의 실리콘 검증 및 생산 검증된 IP 포트폴리오에 가장 잘 반영되어 있습니다. 이 저장소는 하이퍼스케일러뿐만 아니라, 첨단 지능을 IoT, 자동차, 엣지 기기로 확장하기 위한 ‘피지컬 AI(Physical AI)’ 분야에서도 점점 더 주목받고 있습니다. 이러한 생산 검증된 빌딩 블록을 제공함으로써 TSMC는 1조 개의 트랜지스터로 구성된 시스템으로 가는 길이 IP 검증의 물리학이 아니라 창의성에 의해 좌우되도록 보장합니다.
Advanced Silicon and the 3D Packaging Backbone
In the AI era, the “one size fits all” approach to manufacturing has been discarded in favor of aggressive Design-Technology Co-Optimization (DTCO). By concurrently refining process, library, and design flow, TSMC’s roadmap delivers a 2.3X power efficiency gain from the current N3P node toward future architectures like A14.
AI 시대에 ‘일률적인(one size fits all)’ 제조 방식은 폐기되었으며, 대신 적극적인 설계-기술 공동 최적화(DTCO)가 채택되었습니다. 공정, 라이브러리, 설계 플로우를 동시에 개선함으로써 TSMC의 로드맵은 현재의 N3P 노드에서 미래의 A14 같은 아키텍처로 나아가는 과정에서 2.3배의 전력 효율 향상을 제공합니다.
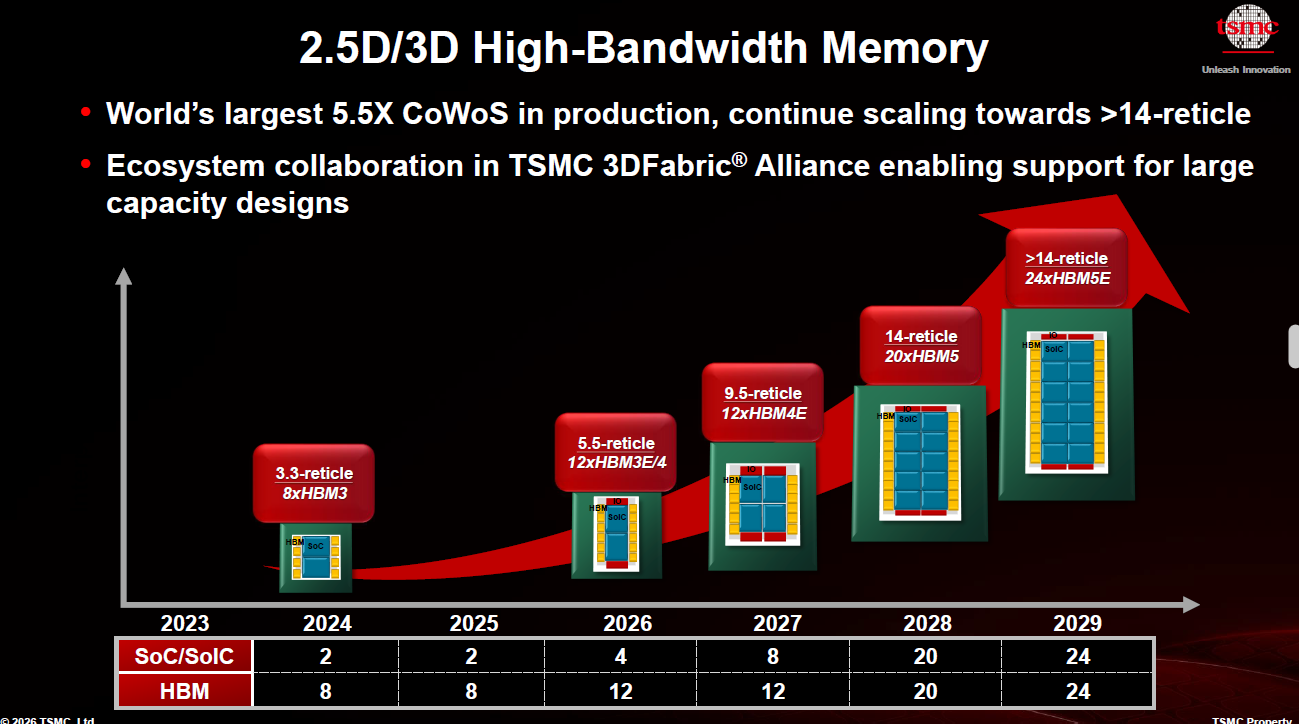
The real breakthrough, however, lies in circumventing the reticle limit. TSMC’s CoWoS® platform is scaling from 3.3-reticle designs to massive packages exceeding 14-reticles. For those visiting the OIP pavilion, the physical 9.5-reticle design on display serves as a tangible milestone of this progress. By 2029, these massive platforms will support 24x HBM5E stacks, enabled by the compounding effect of SoIC (System-on-Integrated-Chips) logic stacking.
그러나 진정한 돌파구는 레티클(reticle) 한계를 우회하는 데 있습니다. TSMC의 CoWoS® 플랫폼은 3.3레티클 설계에서 14레티클을 초과하는 대형 패키지로 확장되고 있습니다. OIP 파빌리온을 방문하는 사람들에게 전시된 물리적인 9.5레티클 설계는 이러한 진보의 구체적인 이정표 역할을 합니다. 2029년까지 이러한 거대 플랫폼은 SoIC(System-on-Integrated-Chips) 로직 적층의 복합적 효과를 바탕으로 24개의 HBM5E 스택을 지원할 것입니다.
Staggering gains are ongoing, from a trajectory moving from a standard SoC on N7 in 2024 to a complex SoIC A14+A14 stack by 2029.
- A 48X increase in transistor count within a single CoWoS package over this 5-year window.
- An 87X surge in total compute capacity, defined specifically as Transistors × Speed @ Power (normalized performance within a power envelope).
2024년 N7의 표준 SoC에서 2029년 복잡한 SoIC A14+A14 스택으로 이어지는 궤적에 걸쳐 놀라운 발전이 진행 중입니다.
- 5년 동안 단일 CoWoS 패키지 내 트랜지스터 수 48배 증가
- 총 연산 능력(전력 범위 내 정규화된 성능인 트랜지스터 × 속도 @ 전력으로 구체적으로 정의됨) 87배 폭증
Next-Generation Memory and Connectivity: HBM5 and Silicon Photonics
As AI workloads move from massive training clusters to “Physical AI” and agentic inference at the edge, memory architecture must become more efficient. TSMC is recognizing key partners (SK Hynix, Micron, and Samsung) for their collaboration on the HBM5 standard. By utilizing the TSMC N3P process for the HBM5 base die, the industry is achieving a critical doubling of bandwidth per energy unit.
AI 워크로드가 대규모 학습 클러스터에서 ‘피지컬 AI’ 및 엣지의 에이전틱 추론으로 이동함에 따라, 메모리 아키텍처는 더욱 효율화되어야 합니다. TSMC는 HBM5 표준 협력에 대해 SK하이닉스, 마이크론, 삼성 등 주요 파트너들에게 경의를 표하고 있습니다. HBM5 베이스 다이에 TSMC N3P 공정을 활용함으로써, 산업계는 에너지 단위당 대역폭을 결정적으로 두 배로 늘리고 있습니다.
On the connectivity front, the TSMC-COUPE™ (Compact Universal Photonic Engine) platform is addressing the looming “interconnect wall.” By integrating co-packaged optics and micro-ring modulators (MRM), TSMC is scaling bandwidth density from current 200Gbps production modulators toward a target of 4Tbps/mm by 2030.
연결성 측면에서는 TSMC-COUPE™(Compact Universal Photonic Engine) 플랫폼이 다가오는 ‘상호 연결 벽(interconnect wall)’ 문제를 해결하고 있습니다. 공동 패키징 광학(co-packaged optics)과 마이크로 링 변조기(MRM)를 통합함으로써, TSMC는 대역폭 밀도를 현재의 200Gbps 생산 변조기에서 2030년까지 4Tbps/mm 목표로 확장하고 있습니다.
Designing “AI for AI”: The Agentic Shift
The most profound shift discussed at the forum was the “virtuous cycle”: using AI to design better chips, which in turn drive more sophisticated AI models.
포럼에서 논의된 가장 심오한 변화는 ‘선순환(virtuous cycle)’이었습니다. 즉, 더 나은 칩을 설계하기 위해 AI를 사용하고, 이는 다시 더 정교한 AI 모델을 구동하는 것입니다.
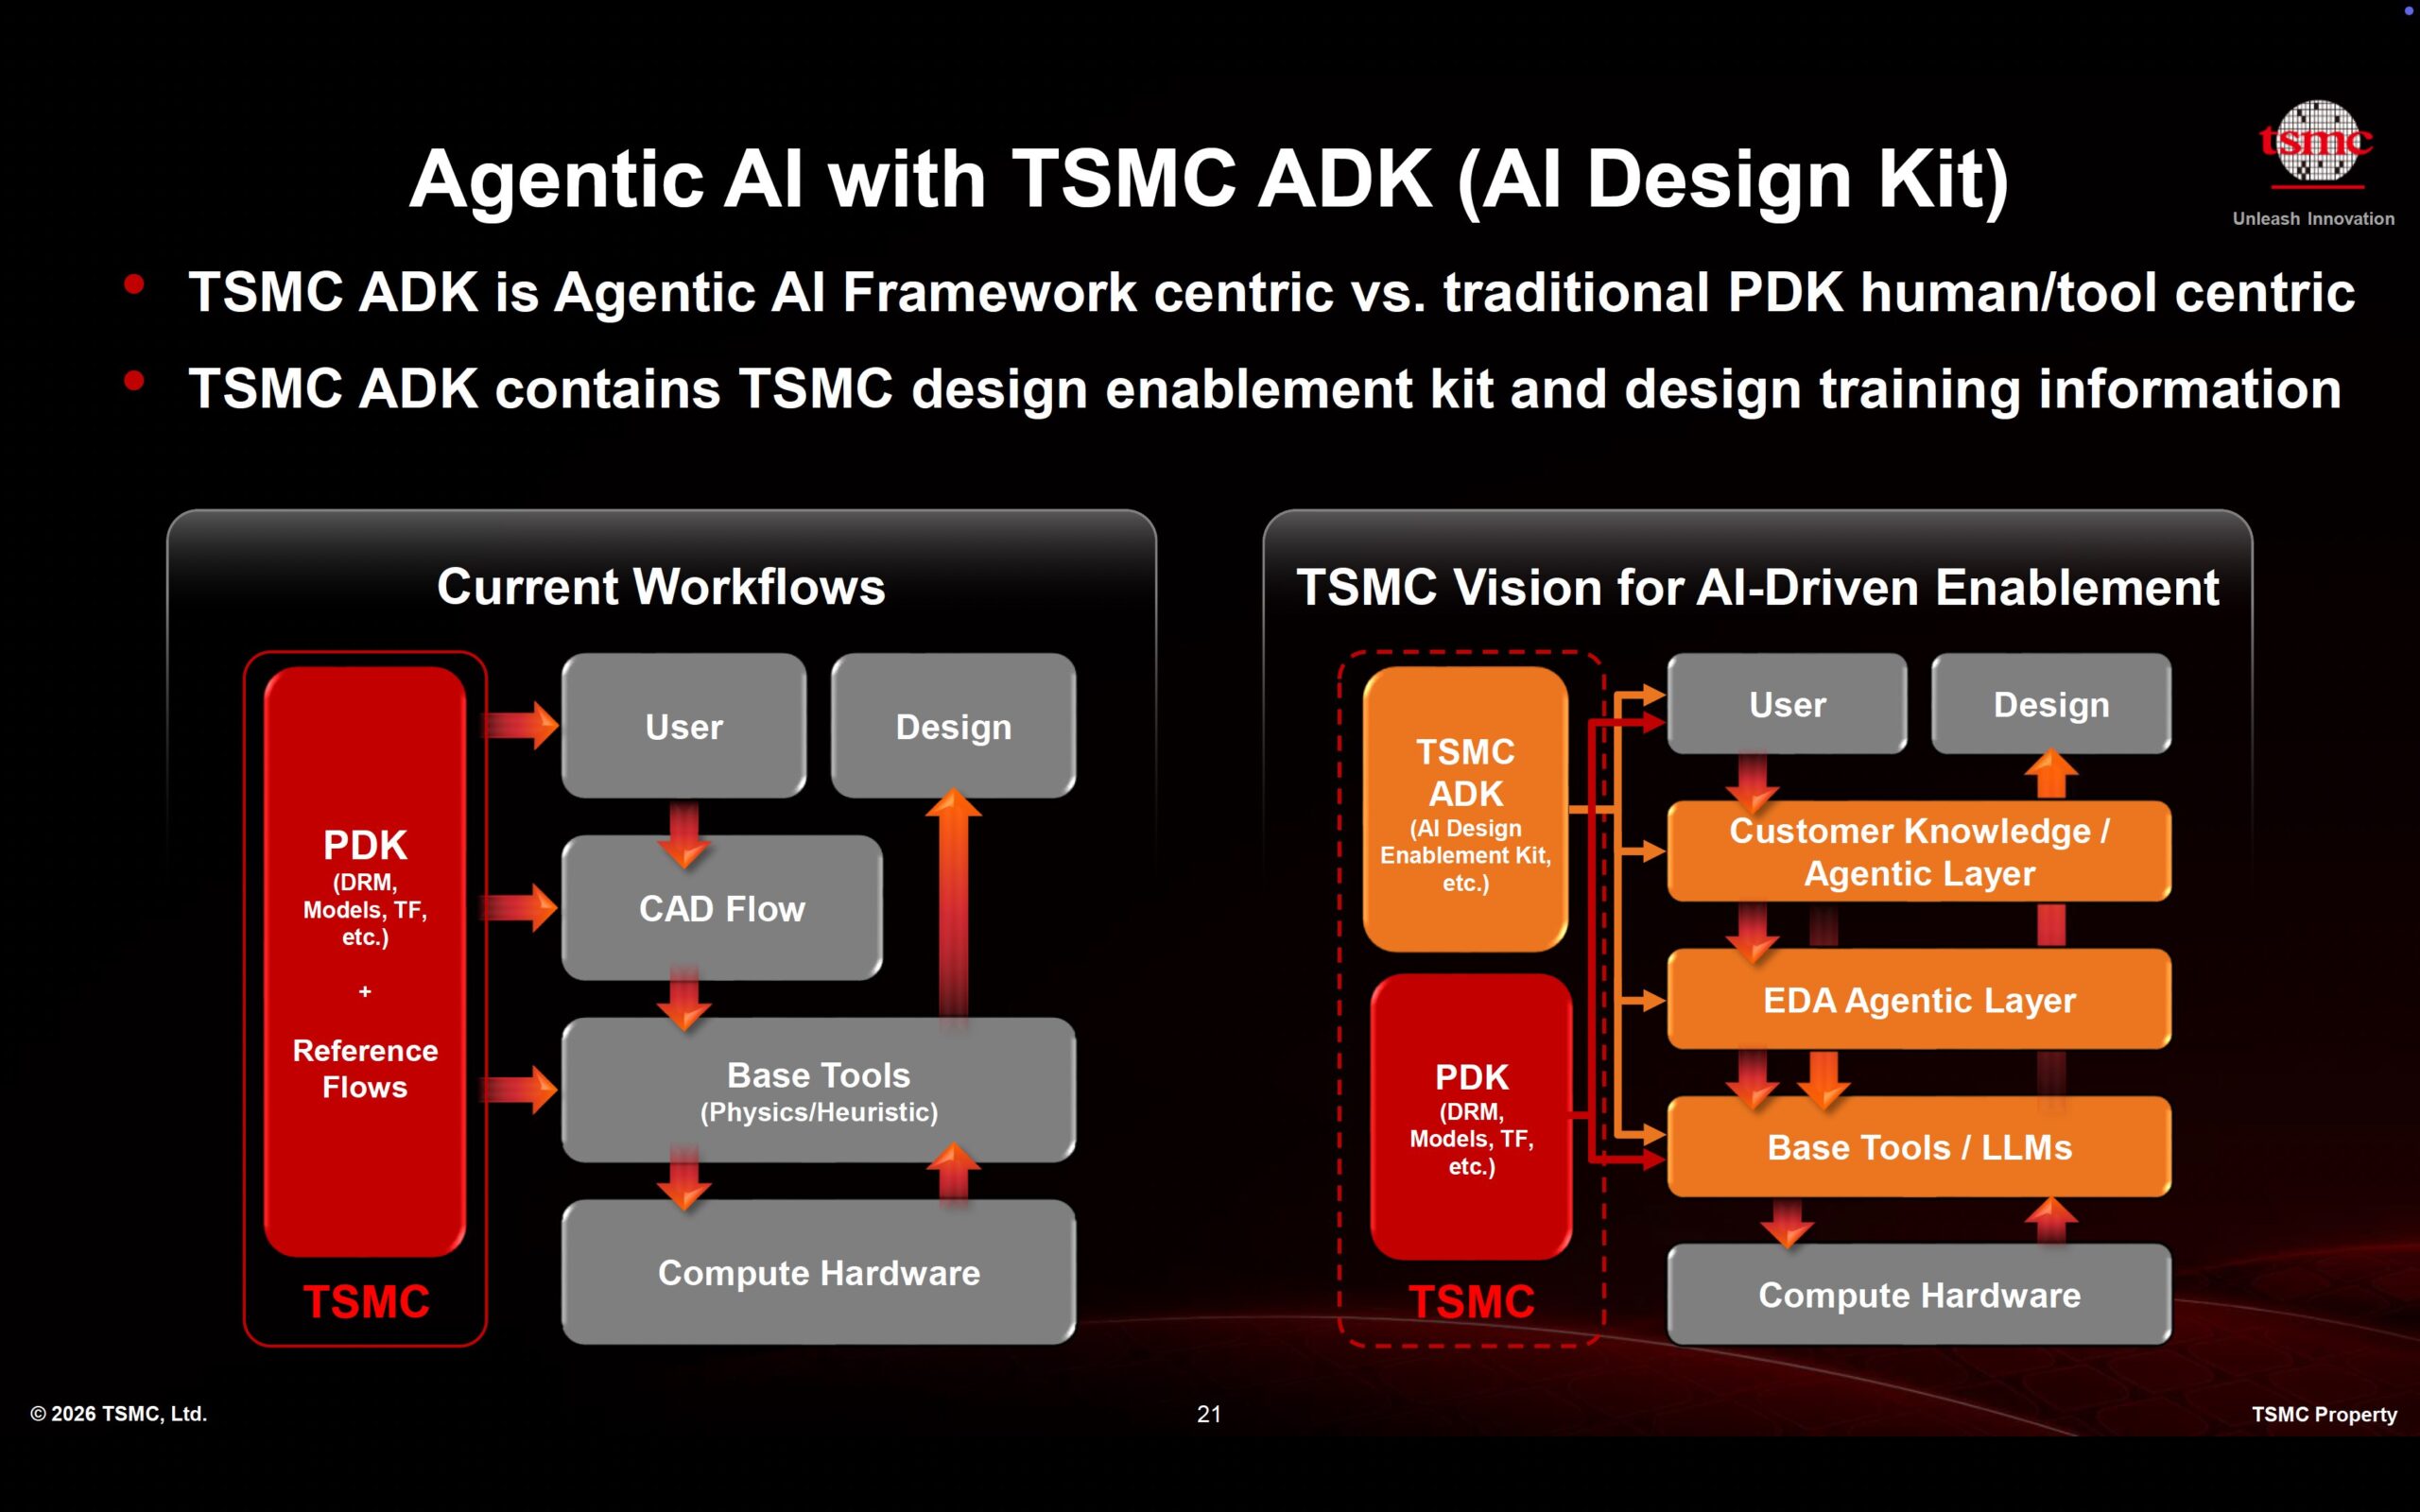
TSMC is evangelizing a transition from the traditional human-centric PDK (Process Design Kit) to the TSMC ADK (AI Design Kit). This is a multi-agent framework where AI agents self-learn from TSMC’s technology learning layers (cell selection, pin escapes and routing strategies) to orchestrate workflows autonomously.
TSMC는 전통적인 인간 중심의 PDK(공정 설계 키트)에서 TSMC ADK(AI 디자인 키트)로의 전환을 전파하고 있습니다. 이는 AI 에이전트가 TSMC의 기술 학습 레이어(셀 선택, 핀 이스케이프 및 라우팅 전략)로부터 스스로 학습하여 워크플로우를 자율적으로 조율하는 멀티 에이전트 프레임워크입니다.
Industry leaders are already seeing the impact through specific agentic tools:
- Digital Design: Using Cadence InnoStack and Synopsys AutoPilot, designers are seeing a 3-5X productivity boost in Place and Route (P&R) iterations.
- Mixed-Signal/Analog: Through tools like Cadence ViraStack and Synopsys Custom Compiler Autopilot, design migration (e.g., N5 to N3 VCO) has achieved a 6X productivity gain.
업계 리더들은 이미 특정 에이전틱 툴을 통해 그 영향을 체감하고 있습니다.
- 디지털 디자인: Cadence InnoStack과 Synopsys AutoPilot을 사용하여 설계자는 P&R(Place and Route) 반복 작업에서 3~5배의 생산성 향상을 경험하고 있습니다.
- 혼성신호/아날로그: Cadence ViraStack과 Synopsys Custom Compiler Autopilot 등의 툴을 통해 설계 마이그레이션(예: N5에서 N3 VCO로)에서 6배의 생산성 향상을 달성했습니다.
Furthering this “AI-native” push, the OIP “Emerging Technologies Alley” featured six hand-picked startups vetted specifically for their innovations in AI-based EDA and IP, signaling a move to bring “AI-first” smaller players into the inner circle of the ecosystem.
이러한 ‘AI 네이티브’ 추진을 이어가기 위해, OIP ‘신흥 기술 골목(Emerging Technologies Alley)’에는 AI 기반 EDA 및 IP 혁신을 기준으로 특별히 엄선된 6개의 스타트업이 참여하여, ‘AI 퍼스트’ 소규모 플레이어들을 생태계의 핵심으로 끌어들이려는 움직임을 보여주었습니다.
System-Level Co-Optimization: From Silicon to SuperPOD
To support trillion-transistor architectures, TSMC is looking beyond the die to the entire rack through STCO (System-Technology Co-Optimization). This holistic approach treats the AI SuperPOD as a single unit of design.
1조 개의 트랜지스터 아키텍처를 지원하기 위해, TSMC는 STCO(시스템-기술 공동 최적화)를 통해 다이를 넘어 전체 랙을 바라보고 있습니다. 이 전체론적 접근 방식은 AI 슈퍼포드를 단일 설계 단위로 취급합니다.
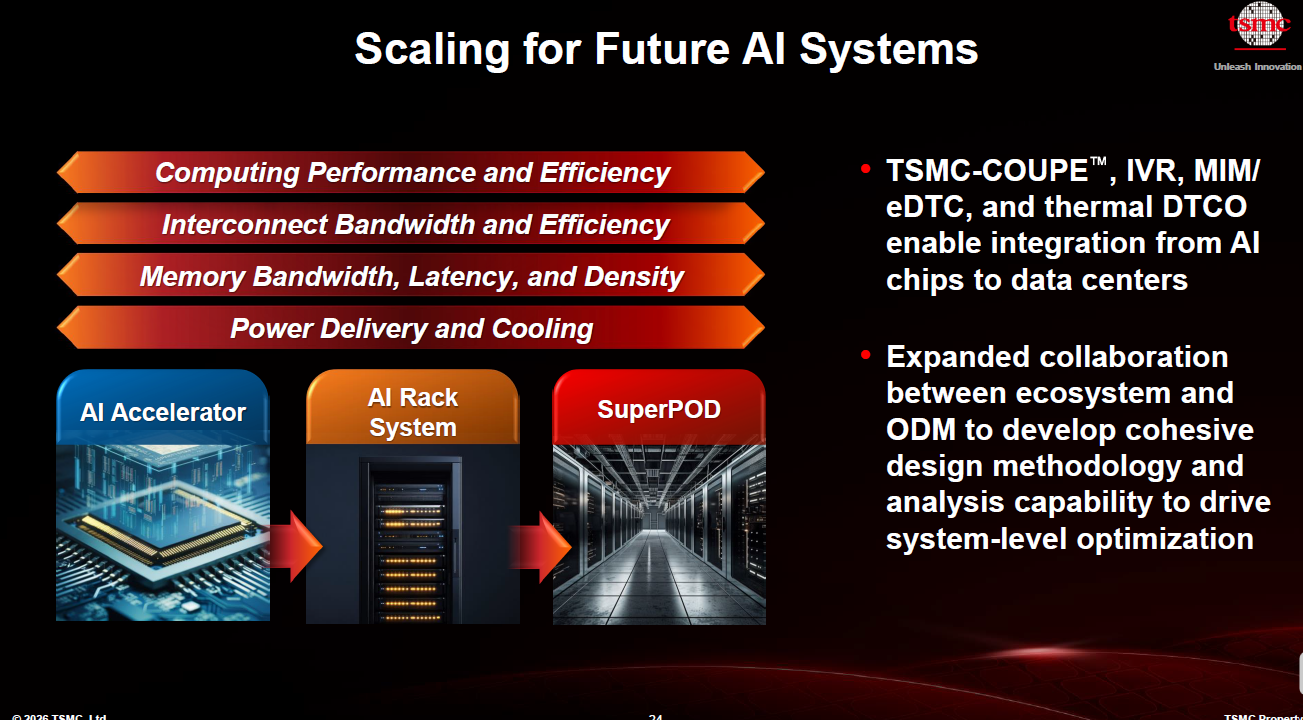
Optimizing a rack-scale system requires more than just logic scaling; it necessitates advanced power delivery and thermal management. TSMC is integrating Integrated Voltage Regulators (IVR), Metal-Insulator-Metal (MIM) capacitors, and Deep Trench Capacitors (eDTC) to stabilize power delivery, while applying thermal DTCO to manage the extreme heat density of next-generation AI accelerators.
랙 규모의 시스템을 최적화하려면 단순히 로직 미세화 이상의 작업이 필요하며, 고급 전력 공급과 열 관리가 필수적입니다. TSMC는 전력 공급을 안정화하기 위해 통합 전압 조정기(IVR), 금속-절연체-금속(MIM) 커패시터, 심층 트렌치 커패시터(eDTC)를 통합하는 동시에, 차세대 AI 가속기의 극심한 열 밀도를 관리하기 위해 열 DTCO를 적용하고 있습니다.
Summary
The trillion-transistor era rests on three strategic pillars:
- Relentless Logic and Packaging Innovation: Pushing the limits of CoWoS scaling and A14 transistor density.
- Radical Design Cycle Acceleration: Implementing the “Agentic AI” shift via the TSMC ADK to compress years of design work into months.
- Holistic System-Wide Optimization: Utilizing STCO to align silicon, power delivery, and thermal management into a cohesive system.
1조 트랜지스터 시대는 세 가지 전략적 기둥을 바탕으로 합니다.
- 끊임없는 로직 및 패키징 혁신: CoWoS 스케일링과 A14 트랜지스터 밀도의 한계 돌파
- 급진적인 설계 주기 가속화: TSMC ADK를 통한 “에이전틱 AI” 전환으로 수년 걸리던 설계 작업을 수개월로 단축
- 전체론적 시스템 전반의 최적화: STCO를 활용해 실리콘, 전력 공급, 열 관리를 응집력 있는 시스템으로 정렬
As the OIP ecosystem enters its third decade, it remains the vital infrastructure for this Intelligence Revolution. The combination of agentic design flows and massive 3D integration marks the most significant architectural inflection point in a generation.
OIP 생태계가 3세대에 진입함에 따라, 이 플랫폼은 여전히 이 지능 혁명을 위한 필수 인프라로 자리 잡고 있습니다. 에이전틱 설계 플로우와 거대한 3D 통합의 결합은 한 세대에서 가장 중요한 아키텍처 변곡점을 나타냅니다.



