Tokens Per Watt Over Peak Performance: Retrofitting Heterogeneous Silicon for Production Inference
👉 This is Part 2 of an editorial series on the evolving economics of AI inference. If you missed Part 1, where I broke down the shift toward full-system integration, the lessons from the AI Infra Summit, and the “no forks” open-source philosophy, you can read it HERE: Beyond the Accelerator: Why Silicon Challengers Must Transition to Full-System Infrastructure.
👉 이것은 AI 추론(Inference)의 진화하는 경제학에 관한 사설 시리즈의 제2부입니다. 전체 시스템 통합을 향한 전환, AI 인프라 서밋(AI Infra Summit)에서의 교훈, 그리고 "노 포크(no forks)" 오픈소스 철학을 다룬 제1부를 놓치셨다면 여기에서 읽어보실 수 있습니다: 가속기를 넘어: 실리콘 도전자들이 풀 시스템 인프라로 전환해야 하는 이유.
In my previous post, we explored why the next phase of the AI infrastructure market will be dominated by complete, integrated systems rather than standalone accelerators. But as enterprises transition from casual AI experimentation to large-scale production, the underlying technical arguments must answer to the realities of the corporate balance sheet. This post continues on with the Rebellions story.
이전 글에서는 AI 인프라 시장의 다음 단계가 독립형 가속기보다는 완전하고 통합된 시스템에 의해 주도될 이유를 살펴보았습니다. 그러나 기업들이 가벼운 AI 실험 단계에서 대규모 프로덕션(상용 운영) 단계로 전환함에 따라, 그 이면의 기술적 주장은 기업의 재무제표가 직면한 현실에 부합해야 합니다. 이번 글은 리벨리온(Rebellions)의 이야기로 계속됩니다.
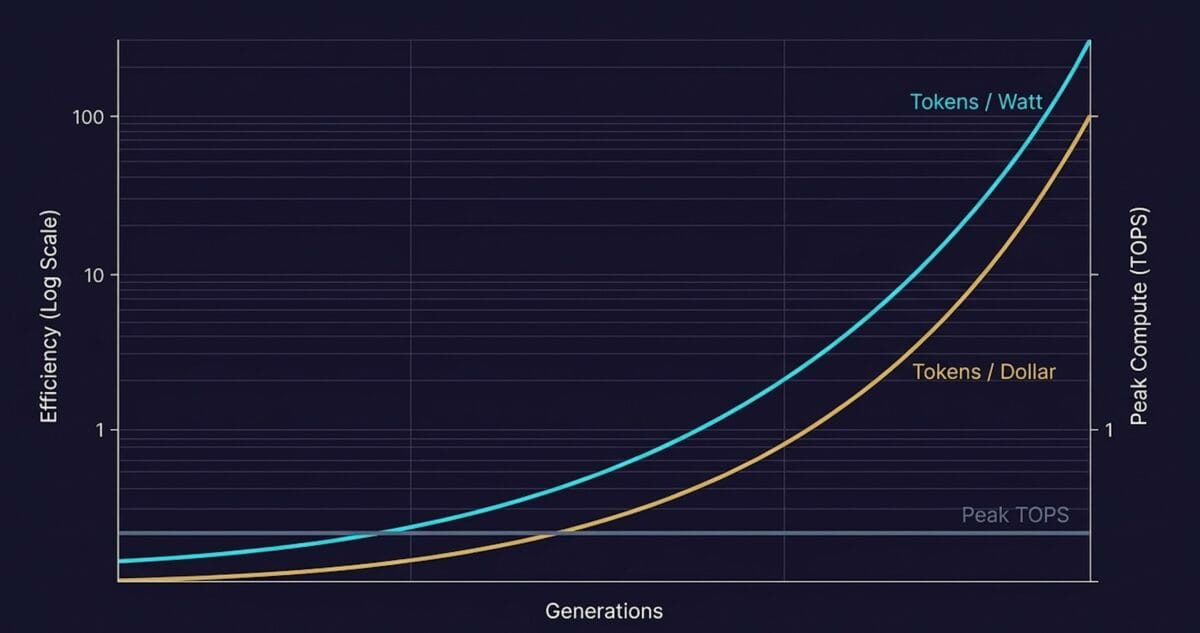
The mathematical argument for specialized inference hardware is becoming difficult for CFOs to ignore. Recent platform data reveals aggressive competitive claims: delivering roughly three times more tokens per dollar, more than double the tokens per watt, and a threefold reduction in overall cost per rack compared to legacy NVIDIA GPU configurations. Just as compelling is the physical profile of the system, which logs a highly optimized four kilowatts of power consumption per deployment unit.
특화된 추론 하드웨어를 뒷받침하는 수학적 논거는 최고재무책임자(CFO)들이 무시하기 어려운 수준이 되고 있습니다. 최근 플랫폼 데이터는 기존 엔비디아(NVIDIA) GPU 구성에 비해 달러당 처리 토큰 수가 약 3배 많고, 와트당 토큰 수는 2배 이상이며, 랙당 전체 비용은 3분의 1로 절감된다는 공격적인 경쟁력 지표를 보여줍니다. 배포 유닛당 전력 소비량이 4킬로와트로 매우 최적화되어 있다는 시스템의 물리적 프로필 또한 마찬가지로 매력적입니다.
While these metrics originate as competitive claims, their broader strategic implication is what matters to infrastructure architects. In the macro-scale game, operating costs dictate survival. When your infrastructure scales across thousands of nodes, the cascading costs of thermal management, floor space, and raw utility draws completely dictate the viability of your AI business model. Peak lab performance becomes a secondary luxury if the baseline economics of a deployment break your budget.
이러한 지표들이 경쟁사 주장에서 비롯된 것이라 하더라도, 인프라 아키텍트들에게 중요한 것은 그 이면에 담긴 광범위한 전략적 의미입니다. 거시적 규모의 경쟁에서 운영 비용은 생존을 좌우합니다. 인프라가 수천 개의 노드로 확장될 때, 발열 관리, 바닥 면적, 전력 소비량에서 발생하는 연쇄적 비용은 AI 비즈니스 모델의 존립 여부를 완전히 결정짓습니다. 배포의 기본 경제성이 예산을 초과해 버린다면, 최고 수준의 실험실 성능은 부차적인 사치에 불과합니다.
Why Benchmarks Distort Production Truths
One of the most vital insights regarding current market positioning is a healthy skepticism toward standard synthetic benchmarking. This perspective is born from deep institutional experience; leadership teams managing these hardware cycles have spent decades evaluating silicon.
현재 시장 포지셔닝과 관련해 가장 중요한 통찰 중 하나는 표준적인 합성 벤치마크(Synthetic benchmarking)에 대한 건전한 회의론입니다. 이러한 시각은 하드웨어 주기를 수십 년간 평가해 온 리더십 팀들의 깊은 현장 경험에서 비롯되었습니다.
Synthetic benchmarks are highly controlled laboratory experiments. They measure isolated performance under variables such as specific model weights, predictable batch sequences, and pristine datasets. Production environments, by contrast, are messy, unpredictable, and highly volatile. Real-world enterprise deployments require flawless uptime, predictable scaling curves under erratic user spikes, robust security profiles, and enterprise-grade resilience. Most importantly, they have to support a viable business proposition.
합성 벤치마크는 고도로 통제된 실험실 실험입니다. 이는 특정 모델 가중치, 예측 가능한 배치 시퀀스, 그리고 정제된 데이터셋 같은 변수들 속에서 고립된 성능을 측정합니다. 반면 프로덕션 환경은 그와 달리 복잡하고 예측 불가능하며 변동성이 큽니다. 실제 기업 배포 환경에서는 완벽한 가동 시간, 예측 불가능한 사용자 급증 상황에서도 흔들리지 않는 예측 가능한 확장 곡선, 강력한 보안 프로필, 그리고 기업용 수준의 탄력성이 요구됩니다. 무엇보다도, 실현 가능한 비즈니스 명분을 뒷받침해야 합니다.
The pitfalls of chasing superficial metrics can be seen in a stark production anecdote: a development organization observed an order-of-magnitude spike in the volume of raw code generated by its AI tools. However, when management looked closer at the actual production environment, the volume of code committed and deployed remained completely flat.
표면적인 지표를 좇을 때의 함정은 한 개발 조직의 극단적인 프로덕션 일화에서 잘 드러납니다. AI 도구에 의해 생성된 원시 코드의 양이 자릿수 단위로 급증한 것을 목격한 것입니다. 그러나 경영진이 실제 프로덕션 환경을 자세히 들여다보았을 때, 실제로 커밋되고 배포된 코드의 양은 완전히 정체되어 있었습니다.
The lesson is a vital reality check for the C-suite: churning out more tokens does not inherently equal true enterprise productivity. For organizations scaling AI across their operations, the metric that matters is business outcome. In other words, what the infrastructure actually empowers the enterprise to achieve.
이 교훈은 C-suite(최고 경영진)에게 꼭 필요한 현실적 경각심을 줍니다. 단순히 더 많은 토큰을 찍어내는 것이 곧 진정한 기업 생산성으로 직결되는 것은 아닙니다. 오퍼레이션 전반에 걸쳐 AI를 확장하는 조직에게 중요한 지표는 비즈니스 결과물입니다. 즉, 인프라가 실제로 기업의 성취를 어떻게 뒷받침하느냐 하는 것입니다.
Production Proof: From SK Telecom to Sovereign Air-Gaps
Rather than building complex infrastructure in a vacuum and searching for a problem to solve, Rebellions and SK Telecom built their framework around a distinct internal corporate bottleneck: customer service applications and heavy textual workloads.
복잡한 인프라를 진공 상태에서 구축한 뒤 해결해야 할 문제를 찾아 나서는 대신, 리벨리온과 SK텔레콤은 명확한 사내 비즈니스 병목 현상, 즉 고객 센터 애플리케이션과 무거운 텍스트 워크로드를 중심으로 프레임워크를 구축했습니다.
The resulting deployment bypassed the standard GPU route, creating an operational profile that proved faster, cheaper, and vastly more scalable than the telecom giant’s previous infrastructure. Today, that foundational architecture has evolved into a full-scale external commercial service, processing roughly 50 million API calls per day for businesses across South Korea.
그 결과 탄생한 배포 환경은 표준적인 GPU 경로를 우회하여, 이 통신 거인의 이전 인프라보다 더 빠르고 저렴하며 훨씬 확장성이 뛰어난 운영 프로필을 입증해 냈습니다. 오늘날 그 기초 아키텍처는 전면적인 대외 상용 서비스로 진화하여, 한국 전역의 기업들을 위해 하루에 약 5,000만 건의 API 호출을 처리하고 있습니다.
This same playbook is driving their push into Sovereign AI—giving local organizations and governments absolute custody over their computing stacks. In partnership with KT Cloud, Rebellions has designed a secure, air-gapped AI infrastructure solution specifically tailored for mission-critical government workloads. Built entirely at rack scale and utilizing OpenStack for robust enterprise orchestration, the system is designed for environments where data security and operational isolation are non-negotiable. By building systems capable of surviving the strict parameters of national government workloads, a highly reliable blueprint is established for enterprise clients in highly regulated sectors like banking, healthcare, and critical infrastructure.
이와 동일한 플레이북이 로컬 조직과 정부가 컴퓨팅 스택에 대한 절대적인 통제권을 갖도록 하는 '소버린 AI(Sovereign AI)' 분야로의 진출을 이끌고 있습니다. KT클라우드와의 파트너십을 통해 리벨리온은 정부의 미션 크리티컬 워크로드에 특화된 안전하고 에어갭(외부망 차단)된 AI 인프라 솔루션을 설계했습니다. 완전히 랙 단위로 구축되었으며 강력한 기업용 오케스트레이션을 위해 오픈스택(OpenStack)을 활용한 이 시스템은 데이터 보안과 운영 격리가 절대적으로 타협될 수 없는 환경을 위해 설계되었습니다. 국가 정부 기관의 엄격한 매개변수를 견뎌낼 수 있는 시스템을 구축함으로써, 뱅킹, 헬스케어, 핵심 인프라와 같이 규제가 엄격한 분야의 기업 고객들을 위한 높은 신뢰성의 청사진이 마련된 것입니다.
The Case for Heterogeneous AI
Underlying this entire strategy is a broader, inevitable prediction about the future of AI infrastructure: computing will become increasingly heterogeneous. The idea that a single type of monolithic processor should dominate every single layer of the AI computing stack is an antiquated relic of early market architecture. Different workloads, fluctuating sequence lengths, and varied application budgets require a flexible blend of processing units, systems, models, and software.
이 전체 전략의 기저에는 AI 인프라의 미래에 대한 보다 광범위하고 피할 수 없는 예측이 깔려 있습니다. 바로 컴퓨팅이 점점 더 이종화(Heterogeneous)될 것이라는 점입니다. 단일 유형의 단일체(Monolithic) 프로세서가 AI 컴퓨팅 스택의 모든 단계를 지배해야 한다는 생각은 초기 시장 아키텍처의 구시대적 유물입니다. 서로 다른 워크로드, 변동하는 시퀀스 길이, 그리고 다양한 애플리케이션 예산에는 프로세싱 유닛, 시스템, 모델, 그리고 소프트웨어의 유연한 조합이 필요합니다.
This philosophy is steering international footprints, highlighted by Rebellions’ partnership with AIand, a prominent Japan-based AI inference service provider focused entirely on heterogeneous infrastructure. The ambitious rollout plans call for deployment across five independent data centers, introducing 40 megawatts of raw capacity and up to 100 integrated rack-scale systems.
이러한 철학은 이종 인프라에 전적으로 초점을 맞춘 일본 기반의 유력 AI 추론 서비스 제공사인 AIand와의 파트너십을 통해 강조되듯이, 국제적 입지를 주도하고 있습니다. 야심 찬 출시 계획에 따라 5개의 독립된 데이터 센터에 걸쳐 40메가와트의 원시 용량과 최대 100개의 통합 랙 스케일 시스템을 배포할 예정입니다.
In this heterogeneous future, the power shifts back to the operators. Infrastructure teams will no longer be locked into a single ecosystem; instead, they can select the most appropriate accelerator for a particular application based on performance, economics, power consumption, availability, and operational requirements. Crucially, such an approach allows organizations to make greater use of their existing legacy infrastructure while adding new capabilities incrementally, rather than forcing a costly rip-and-replace architecture.
이러한 이종화된 미래에서는 주도권이 다시 운영자에게 넘어갑니다. 인프라 팀들은 더 이상 단일 생태계에 갇혀 지내지 않고, 성능, 경제성, 전력 소비, 가용성 및 운영 요구사항에 따라 특정 애플리케이션에 가장 적합한 가속기를 선택할 수 있게 됩니다. 결정적으로 이러한 접근 방식을 통해 조직들은 비용이 많이 드는 전면 교체(Rip-and-replace) 아키텍처를 강제당하는 대신, 새로운 기능을 점진적으로 추가하면서 기존의 레거시 인프라를 더 효과적으로 활용할 수 있습니다.
Designing for Deployment, Not Experiments
Ultimately, the market is moving past the phase of unconstrained AI experimentation and stepping firmly into large-scale production. Performance will always remain a pillar of the equation. But as inference workloads scale, organizations must evaluate the complete picture: power constraints, capital expenditure, operating expenditure, physical space, reliability, software compatibility, and business outcomes.
궁극적으로 시장은 제약 없는 AI 실험 단계를 지나 대규모 프로덕션 단계로 단단히 발을 들여놓고 있습니다. 성능은 언제나 방정식의 핵심 기둥으로 남을 것입니다. 그러나 추론 워크로드가 확장됨에 따라 조직들은 전력 제약, 자본적 지출(CapEx), 운영적 지출(OpEx), 물리적 공간, 신뢰성, 소프트웨어 호환성, 그리고 비즈니스 성과라는 전체 그림을 평가해야 합니다.
The pitch is less about chasing a fleeting headline benchmark and far more about the unglamorous work of deployment. AI inference has officially become an infrastructure category in its own right. The winners in this next phase of the market will have to compete on economics, raw efficiency, openness, and the uncompromising ability to deliver real-world business value.
이번 피치는 일시적인 헤드라인 벤치마크를 쫓는 것이라기보다는 배포라는 빛나지 않지만 묵묵한 작업에 훨씬 가깝습니다. AI 추론은 공식적으로 독자적인 인프라 카테고리가 되었습니다. 이 시장의 다음 단계에서 승리하는 이들은 경제성, 원시 효율성, 개방성, 그리고 실세계의 비즈니스 가치를 전달할 수 있는 타협 없는 역량을 바탕으로 경쟁해야 할 것입니다.
Visit Www.Rebellions.ai to learn more.
자세한 내용은 Www.Rebellions.ai를 방문해 확인해 보세요.



